AI agent observability is the ability to understand what an AI agent did during a run, why it produced a particular outcome, which tools and models it called, how long every action took, and how much of the available resources it used. SimplAI Observability connects project-level run analytics with detailed traces, tree and flow visualizations, waterfall latency analysis, voice-call review, and exportable data in one organized experience.
For enterprise teams, that means a faster path from an operational signal—such as a failed run or unusual latency—to the exact action that needs investigation.
AI agents create a new observability challenge
Traditional application monitoring is designed for relatively predictable execution paths. AI agents behave differently. A single run may invoke an LLM several times, choose among multiple tools, create nested calls, wait for human approval, or take a different route based on the context it receives.
That flexibility is what makes agents useful. It is also what makes them difficult to operate without purpose-built visibility.
A status code can tell a technical team that a run failed. It cannot, by itself, explain whether the issue began in an LLM call, a tool invocation, an unexpected input, a repeated step, or a slow dependency. A project dashboard can reveal a lower success rate, but the team still needs a connected route from that metric to the evidence inside the execution.
SimplAI Observability is designed around that route. Teams can begin with the overall health of agent runs and progressively move into sources, tools, individual traces, nested call structures, input and output data, latency, completion status, and credit usage.
Enterprise takeaway: Observability turns an AI agent from a black box into an inspectable operational system.
What is SimplAI Observability?
SimplAI Observability is a unified environment for monitoring, analyzing, and understanding agent runs across a project. It gives teams multiple levels of visibility:
- A summary of total runs within a selected date range
- Completed, failed, and pending-approval run status
- Success-rate indicators for identifying patterns
- Sankey analysis of run sources, including API, platform, and project tools
- Agent- and tool-level completion and failure breakdowns
- Detailed, color-coded execution traces
- Input and output inspection in JSON and YAML
- Time, latency, completion status, and credit usage for individual actions
- Tree, flow, and waterfall views of agent execution
- Voice-agent recordings with corresponding trace and latency information
- Excel export for deeper analysis and reporting
This layered approach supports different enterprise roles. An engineering leader can review run health. A developer can inspect an individual tool call. An SRE or platform engineer can investigate latency. An operations team can identify approval backlogs. A voice team can connect the caller’s experience with the execution behind the conversation.
From project health to root cause in one workflow
An effective investigation should not require teams to jump between several disconnected tools. SimplAI’s observability workflow follows a natural progression:
- Define the period you want to investigate.
- Review the health and status of runs.
- Identify the source, agent, or tool associated with a pattern.
- Open the relevant run.
- Inspect its trace and individual actions.
- Choose the visualization that best answers the question.
- Use latency, status, and credit information to guide optimization.
- Verify the impact in subsequent runs.
The sections below show exactly how to use that workflow.
Step-by-step: How to use SimplAI Observability
Stage 1: Open Observability and define the scope
Step 1 : Open Observability from the dashboard. Navigate to the Observability area for your project.
Step 2 : Select the environment or view. Click Observe, then select Test to open the immersive run-summary screen.
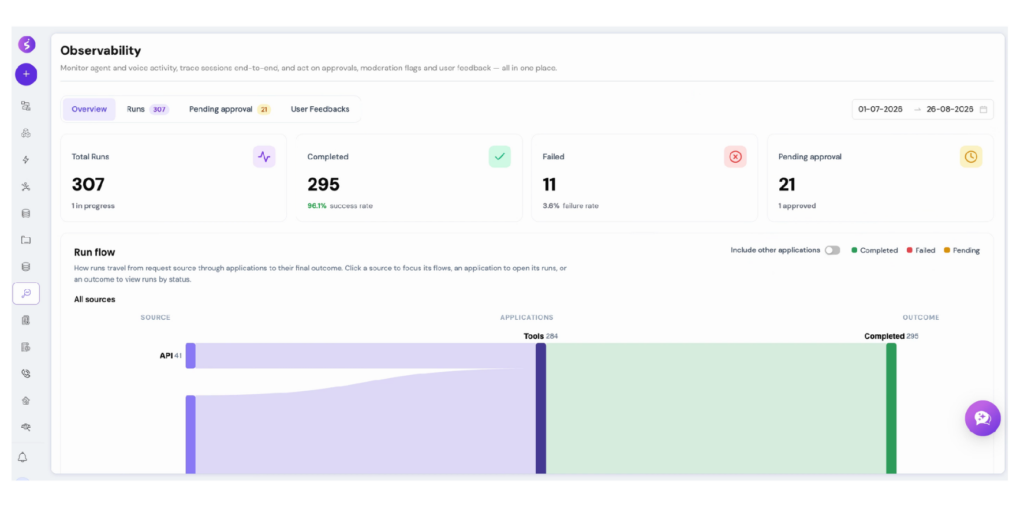
Step 3 : Set the date range. Choose the period you want to analyze. A defined time window keeps the results aligned with a test cycle, release, incident, or operational review.
Stage 2: Monitor run health and locate patterns
Step 4 — Review all agent runs. Compare completed, failed, and approval-pending activity. Use the success indicators to identify changes or recurring patterns that deserve investigation.
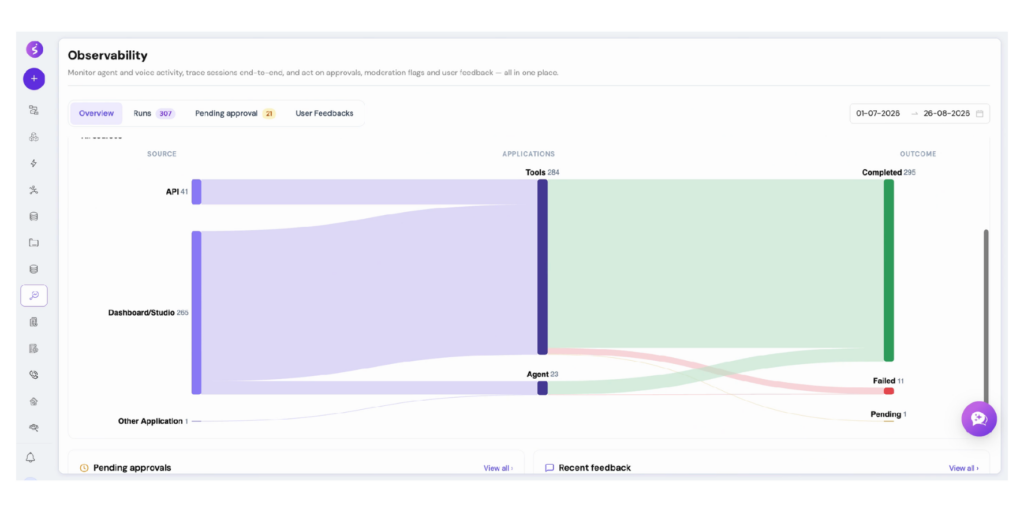
Step 5 — Explore run sources in the Sankey chart. The chart visualizes where runs came from—such as an API, the SimplAI platform, or tools used within the project—and how those runs move toward their outcomes.
Step 6 — Move to the agent or tool level. Sort runs by tool type and compare completion and failure counts. This narrows a project-wide signal to the component most likely to explain it.
Step 7 — Export the current view when needed. Download the data as an Excel file for deeper analysis, reporting, or collaboration outside the platform.
Stage 3: Open a run and inspect the complete trace
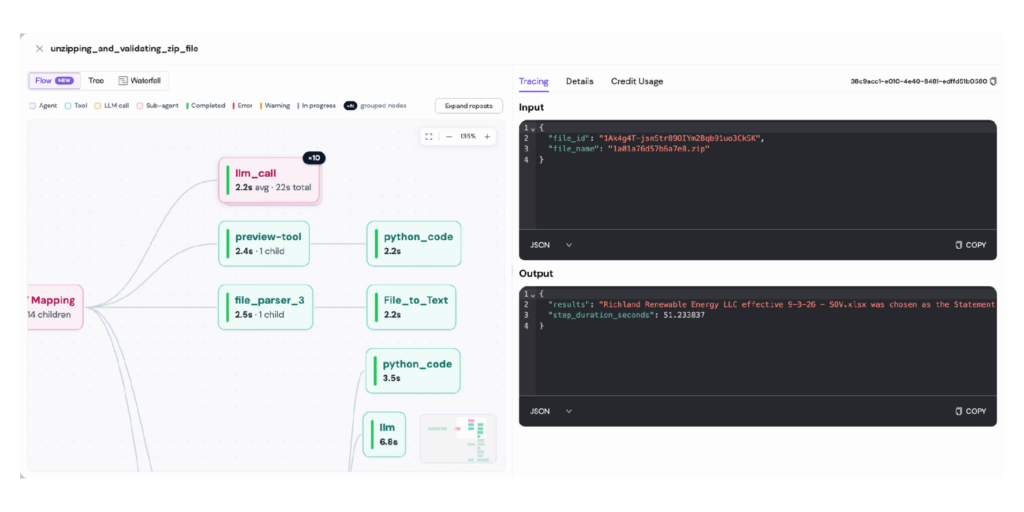
Step 8 — Select an individual run. Open any run to view its detailed trace. Actions are color-coded by tool type, making agent steps, LLM calls, and other invocations easier to distinguish.
Step 9 — Expand the trace. Follow the complete order of operations, including nested actions and repeated calls. This is where a team can see how many times a tool or LLM was invoked during the run.
Step 10 — Select a specific trace action. Review the input and output associated with that call. SimplAI makes the data available in both JSON and YAML formats.
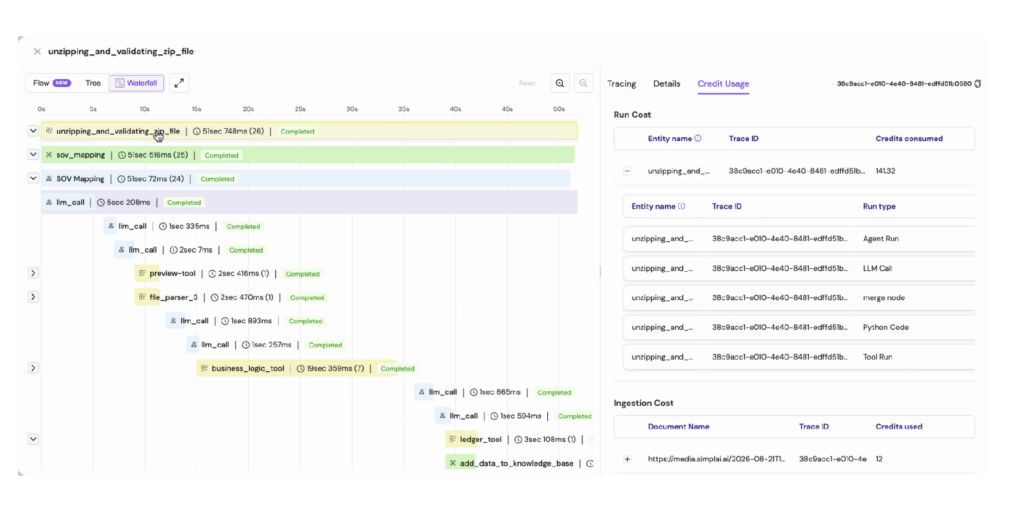
Step 11 — Review operational details. Examine the time, latency, completion status, and credit usage for the selected action. These signals connect behavior with performance and resource consumption.
Stage 4: Choose the right execution model
Step 12 — Use the tree structure for hierarchy. The tree maps how each call leads to another. Expand it to understand nested relationships, tool use, mappings, and repeat calls.
Step 13 — Switch to the waterfall model for latency. The waterfall view shows how long each action takes from start to finish. It is the clearest option when the primary question is, “Where is this run spending time?”
Step 14 — Use tree and flow views for different questions. The tree emphasizes nested-call abstraction. The flow view emphasizes the logical sequence between calls. Switching between them helps teams understand both structure and progression.
Stage 5: Analyze voice-agent runs
Step 15 — Open the voice-agent section. Voice conversations are unique, so SimplAI provides visualizations suited to this interaction model.
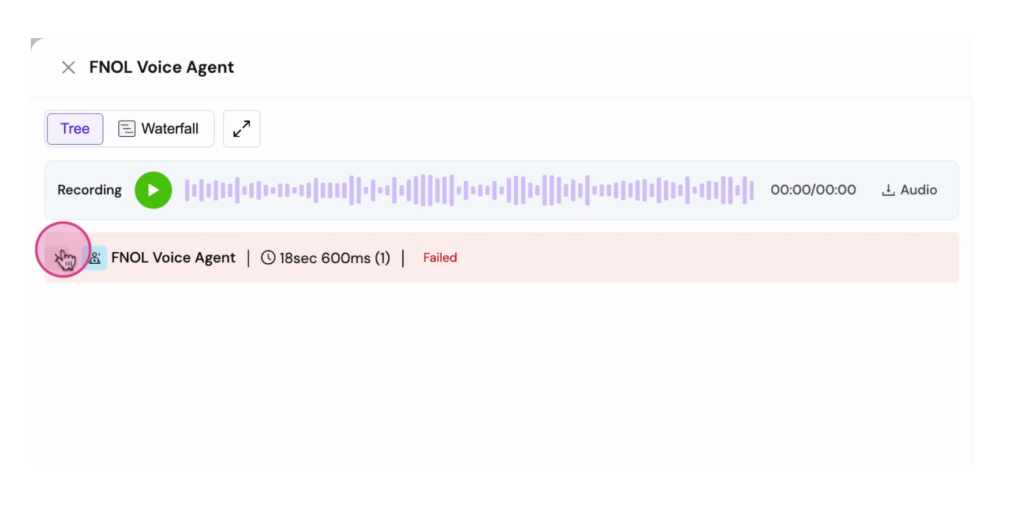
Step 16 — Review individual voice calls. Listen to call recordings and inspect the detailed trace alongside latency, status, and credit information. The recording shows what the person experienced; the trace shows how the agent executed.
Step 17 — Use the voice waterfall view. Switch to the waterfall model to analyze response timing, with latency presented across the call’s actions.
How enterprise teams can use each observability view
Run summary: operational awareness
Use the summary screen for daily monitoring, test reviews, release checks, or incident triage. It answers whether activity is completing as expected and whether failures or pending approvals are becoming concentrated.
Sankey chart: source and pathway analysis
Use the Sankey chart when a project receives runs from several sources or uses multiple tools. It helps teams understand which pathways account for activity and where outcomes diverge.
Detailed trace: execution-level debugging
Use the detailed trace when the team needs evidence. Inputs, outputs, tool order, repeat calls, status, and timing help developers reconstruct the run rather than relying on assumptions.
Tree view: nested-agent logic
Use the tree view to understand parent-child relationships. It is useful for complex executions in which one action triggers several deeper calls.
Flow view: logical sequence
Use the flow view to explain how the run progressed from one action to the next. It provides a straightforward representation for reviewing agent logic with technical and cross-functional stakeholders.
Waterfall view: performance analysis
Use the waterfall view to compare durations across a run. It helps reveal a slow tool call, a lengthy model action, or repeated execution that adds cumulative latency.
Voice view: experience and execution together
Use voice observability when the human experience and system execution must be reviewed as one event. The recording provides conversational context; the trace and waterfall provide technical context.
What should enterprise teams monitor?
The most useful metrics are the ones that lead to action. In SimplAI Observability, teams can focus on:
- Run volume: How many executions occurred during the selected period?
- Completion status: How many completed, failed, or require approval?
- Success patterns: Is performance changing across the selected date range?
- Source distribution: Are runs entering through the API, platform, or particular tools?
- Agent and tool outcomes: Is one component associated with more failures?
- Call frequency: Are tools or LLMs being invoked more often than expected?
- Latency: Which action contributes the most time to the run?
- Credit usage: Which actions account for resource consumption?
- Voice-call behavior: Does the recorded interaction align with the execution trace and timing?
No single metric tells the whole story. Run analytics identify where to look; traces explain what happened; tree and flow models explain structure; waterfall analysis explains time.
A repeatable troubleshooting playbook for technical teams
When an agent run fails or slows down, use this sequence:
- Select the date range surrounding the issue.
- Confirm whether the behavior is isolated or part of a broader pattern.
- Segment activity by source, agent, or tool.
- Open one or more representative runs.
- Expand the trace and follow the call order.
- Inspect the relevant input and output in JSON or YAML.
- Check completion status and repeat-call behavior.
- Switch to the tree view for nested dependencies.
- Switch to the waterfall view for timing.
- Review credit usage where efficiency is part of the investigation.
- Make the change in the agent or workflow.
- compare subsequent runs to verify the effect.
This process reduces the distance between detection and diagnosis. It also creates a shared investigation method across development, platform, operations, and product teams.
From debugging tool to continuous improvement system
Observability is most valuable when it becomes part of the regular agent lifecycle. Teams can use SimplAI before and after deployment:
- During testing, inspect traces to confirm that calls occur in the expected order.
- During release validation, compare completion and failure patterns within a defined period.
- During production operations, monitor run health and investigate unusual behavior.
- During performance work, use waterfall timing to locate latency.
- During optimization, review repeat calls and credit usage.
- During voice-agent reviews, connect recordings with the execution that produced the experience.
- During business or operational reporting, export the current view to Excel.
The result is a closed feedback loop: observe, isolate, understand, improve, and verify.
Why SimplAI Observability matters for enterprise AI operations
Enterprise AI cannot be operated confidently on outputs alone. Technical teams need to understand execution. Leaders need visibility into run health and performance. Operations teams need to distinguish failures from approval-dependent work. Voice teams need to connect system behavior with caller experience.
SimplAI Observability brings those perspectives together without losing the detail required by developers. A team can start with total runs, move through a source or tool pattern, and arrive at an individual JSON or YAML payload inside a trace. The same run can then be examined as a hierarchy, logical flow, or timing waterfall.
That is the difference between knowing that an agent ran and understanding how it operated.
See every run. Understand every action. Improve every agent.
SimplAI Observability gives enterprise and technical teams a clear, actionable view of agent behavior across projects. Monitor completion and failure patterns. Understand where runs originate. Compare agents and tools. Inspect every model and tool invocation. Analyze nested logic and latency. Review voice interactions. Export structured data for deeper analysis.
Explore the Observability experience in your SimplAI dashboard and turn every agent run into an opportunity to learn and improve.
What is AI agent observability?
AI agent observability is the practice of monitoring agent runs and tracing the models, tools, inputs, outputs, status, latency, and resource usage involved in each execution.
How is AI agent observability different from LLM observability?
LLM observability focuses on model interactions. AI agent observability covers the broader execution, including LLM calls, tool invocations, nested actions, approval states, and the complete path of a run.
What is an AI agent trace?
An AI agent trace is an ordered record of the actions performed during a run. It can show model calls, tool invocations, nested relationships, inputs, outputs, timing, status, and repeated calls.
How do you monitor AI agent performance?
Start with run volume, completion, failure, and approval status. Then compare sources, agents, and tools before opening detailed traces and using waterfall timing to investigate performance.
How do you debug a failed AI agent run?
Open the failed run, expand its trace, follow the call order, select the relevant action, inspect its input and output, and review status and latency. Use the tree view when nested calls need clarification.
How can teams find latency in an AI workflow?
Use the waterfall view. It displays the duration of calls from start to finish, making slow actions and accumulated delays easier to identify.
What is the difference between tree, flow, and waterfall traces?
Tree view shows hierarchy, flow view shows logical sequence, and waterfall view shows timing. Together, they explain structure, progression, and performance.
Can SimplAI show LLM and tool calls?
Yes. Detailed traces distinguish action types and show tool invocations, LLM calls, their order, and repeated usage.
Can teams inspect agent inputs and outputs?
Yes. Selecting an individual trace call makes input and output data available in JSON and YAML formats.
Does SimplAI track agent-run latency and credit usage?
Yes. Individual actions include time, latency, completion status, and credit-usage information.
What is voice agent observability?
Voice agent observability combines conversation recordings with the technical trace, status, latency, and credit information associated with each call.
Can SimplAI observability data be exported?
Yes. Teams can download the current view as an Excel file for deeper analysis and reporting.
Who uses AI agent observability in an enterprise?
Engineering, platform, DevOps, SRE, product, operations, voice, and technology-leadership teams can use different levels of observability to monitor health, debug runs, analyze performance, and review outcomes.
Why are success rates not enough for AI agents?
Success rates show the outcome pattern but not the cause. A detailed trace is needed to understand which model, tool, input, output, or nested action influenced an individual run.
How often should teams review agent observability data?
Review frequency should match the operating context. Teams can use the dashboard during testing, release validation, routine operations, incident investigation, and post-change verification.
Author bio