Executive Summary
Choosing the right LLM for an enterprise AI agent is one of the most consequential architectural decisions a team makes. It shapes output quality, tool-calling behaviour, token economics, latency profiles, and how downstream systems process the agent’s responses. Yet most teams make this choice once, early in development, based on published benchmarks that were never designed to reflect real-world agent workflows.
This report documents a controlled head-to-head evaluation of OpenAI GPT-5.5 and Anthropic Claude Opus 4.7, conducted inside SimplAI multi-model agent framework. We ran both models through an identical enterprise task — generating a comprehensive company intelligence profile for Alphabet Inc. (ABC.XYZ) — using the same prompt, the same tools, the same orchestration logic, and the same evaluation rubric. The only variable we changed was the model.
Key findings: GPT-5.5 delivered maximum information density in a single first response and scored 4.25 out of 5 on a strong evaluation trace. Claude Opus 4.7 produced more structured, source-cited, modular outputs and showed a more analyst-like interaction pattern — delivering a concise tabular summary first, then elaborating richly on follow-up. Neither model is categorically superior. The right choice is entirely use-case dependent, and the only way to determine fit is through systematic, multi-trace evaluation.
Why LLM Selection Is an Ongoing Decision, Not a One-Time Choice
The Hidden Cost of Picking a Model and Moving On
When a team starts building an AI agent, the first major decision is which foundation model to use. It feels like a clean, one-time architectural choice. But the reality is more complex. The model you select becomes embedded in your architecture in ways that are easy to underestimate: your system prompts are tuned to that model’s response style, your output parsers are built around its formatting tendencies, your error handlers are calibrated to its failure modes, and your latency SLAs are set against its throughput characteristics.
When a better model is released — or when your current model underperforms on a specific task — switching is not a simple configuration change. It often requires re-prompting, re-testing, and re-validating the entire pipeline. This is the hidden cost of treating model selection as a one-time decision: it creates architectural debt that compounds over time.
SimplAI is designed to remove this friction entirely. In SimplAI, switching models is a single configuration change — every other component of the agent (tools, prompts, orchestration, evaluation) remains identical. This makes genuine model comparison possible, and it makes ongoing model optimization a standard part of the development workflow rather than a disruptive architectural event.
Why Published Benchmarks Are Insufficient
Published benchmarks like MMLU, HumanEval, GPQA, and BIG-Bench are rigorous, peer-reviewed, and useful for comparing raw model capabilities in controlled settings. But they have fundamental limitations when applied to enterprise agent evaluation:
- They test isolated tasks, not pipelines. An agent’s performance depends on how it integrates tool calls, interprets intermediate outputs, and chains reasoning across multiple steps. No standard benchmark captures this.
- They don’t measure output format consistency. For agents feeding downstream systems, consistent output formatting is often as important as factual accuracy. Benchmarks don’t score this.
- They test average-case performance. Enterprise tasks often have specific edge cases — ambiguous inputs, poorly structured documents, incomplete web results — that benchmarks don’t surface.
- They’re designed by labs, not practitioners. The tasks in published benchmarks are chosen to differentiate model capabilities at the margins, not to reflect the specific workflows your team is building.
The implication is direct: the only benchmark that matters for your agent is the one you design and run yourself, against your actual use case, with your actual tools and prompts. That’s exactly what this report documents.
The Evaluation Setup: Architecture, Tools, and Test Conditions
The Agent: Enterprise Company Intelligence
The agent we built for this evaluation is representative of a class of high-value enterprise workflows: structured research and intelligence generation from multiple unstructured sources. This type of agent is used by analyst firms, M&A teams, procurement departments, competitive intelligence units, and investor research desks.
The agent’s primary responsibility was defined precisely in its system prompt: understand user intent and generate a complete, structured company profile for the entered company. The profile was required to cover the following dimensions, each sourced from the public domain:
- Ownership and corporate structure: Shareholders, promoters, subsidiaries, and holding relationships. This requires navigating complex corporate filing data, often in PDF format.
- Products and services: Core product lines, platform ecosystems, hardware offerings, subscription models, and service categories. For a company like Alphabet, this spans consumer, enterprise, developer, and hardware domains.
- Market footprint: Geographic presence, market segments served, and customer base composition. This requires synthesising data from multiple sources with varying levels of granularity.
- Financial overview: Key metrics for fiscal year 2024 including revenue, operating income, margin profile, and segment-level breakdown. Much of this data exists only in PDF filings.
- Recent developments: News, product launches, regulatory events, leadership changes, and strategic announcements from the public domain within the recent period.
- Key management: Executive leadership, board composition, and any recent changes to organisational structure.
- Customers: Major customer segments, enterprise client relationships, and end-user demographics where publicly available.
The Test Company: Why Alphabet Inc. Was the Right Choice
We selected Alphabet Inc. (ABC.XYZ) as our test target for specific reasons. It represents a genuinely difficult information retrieval and synthesis task: the corporate structure is complex (Alphabet as holding company, Google as subsidiary, with multiple other bets under the umbrella), the product portfolio spans dozens of distinct offerings across multiple business models, the financial data is detailed and publicly available in SEC filings, and there is constant news flow requiring recency awareness.
A company that is too obscure would not stress-test the models’ ability to retrieve and synthesise information, since there would be little to find. A company that is too well-known risks both models simply reproducing training data. Alphabet sits in the ideal zone: extremely well-documented, but complex enough that real synthesis, tool use, and structured reasoning are required to produce a high-quality profile.
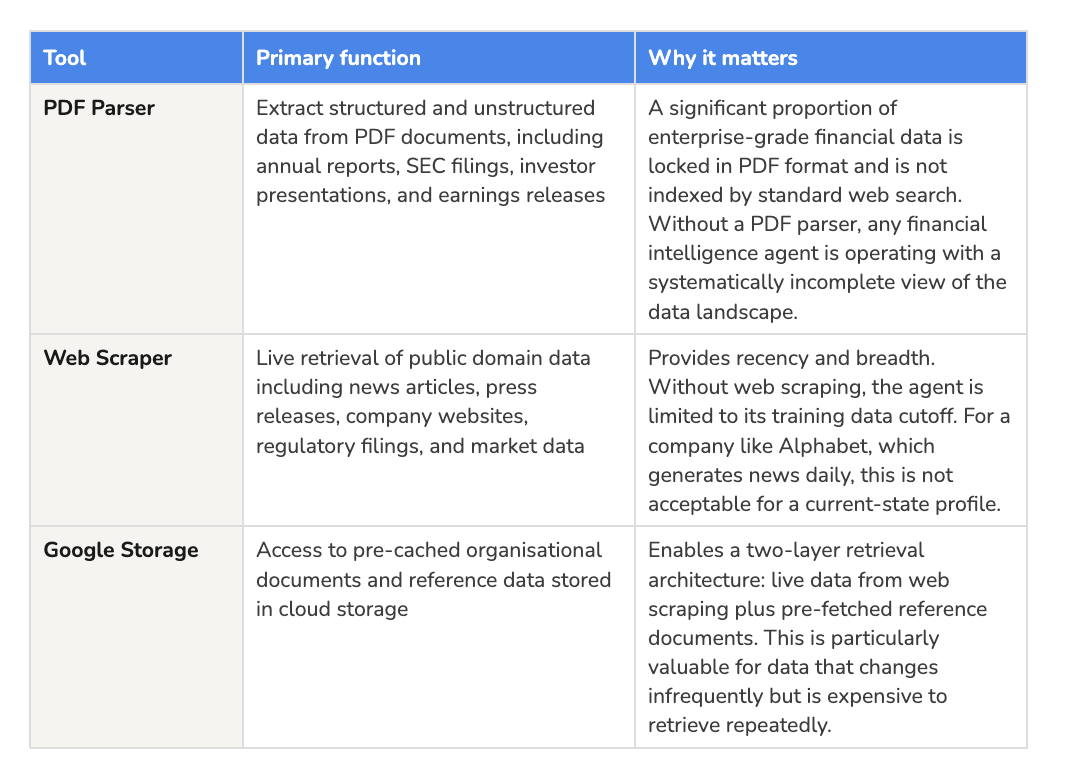
Tools Available to the Agent
Both model versions of the agent had access to exactly the same three tools. No tool was modified, added, or removed between the GPT-5.5 run and the Claude Opus 4.7 run.
The Single-Variable Control
How We Ran the Evaluation in SimplAI
Version Publishing: Creating a Reproducible Baseline
Before running any evaluation, we published each agent configuration as a named version inside SimplAI. Version 1 was labelled “GPT-5.5 version” and Version 2 was labelled “Opus 4.7 version.” Publishing a version before running creates a locked snapshot of the agent’s configuration at that moment — preventing any mid-session drift from contaminating the baseline.
This is an important workflow discipline that many teams skip. If you preview an agent, then publish it, any interaction during the preview session may introduce implicit state changes. Publishing first, then previewing, ensures the evaluation is always running against a known, reproducible configuration.
Configuring the Evaluator
SimplAI’s built-in evaluation system allows teams to configure custom rubrics for scoring agent outputs. We used the AI-assisted evaluator builder, which takes a natural language description of the evaluation goal and suggests an appropriate scoring structure.
Our evaluator description: “Test the quality of output for company profile generation.” The AI-assisted builder suggested a 1–5 numerical scale with defined criteria for each score band, covering:
- Completeness — does the profile cover all required dimensions?
- Accuracy — are the facts, figures, and claims verifiable against public sources?
- Structure — is the output organised in a way that is easy to navigate and consume?
- Source transparency — are claims attributed to identifiable sources?
- Actionability — could a business professional use this output to make informed decisions?
The resulting evaluator was saved as a reusable template, meaning every trace generated by either agent version — now and in the future — is automatically scored against the same criteria. This is what makes longitudinal comparison possible.
Trace Review: Why Aggregate Scores Are Not Enough
Scores alone are a lagging indicator of agent performance. A score of 3.5 could mean many things: the output was comprehensive but poorly structured; or well-structured but factually thin; or excellent on four dimensions and catastrophically wrong on one. Without reading the trace, you cannot know which.
SimplAI logs every trace in full: the tool calls made, the arguments passed to each tool, the intermediate outputs returned, the model’s reasoning between steps, and the final output. When Claude Opus 4.7’s initial trace showed a partial-success result, it was the trace review that revealed the specific limitations — providing actionable diagnostic information rather than just a number.
Output Comparison: GPT-5.5 vs Claude Opus 4.7
First-Response Behaviour
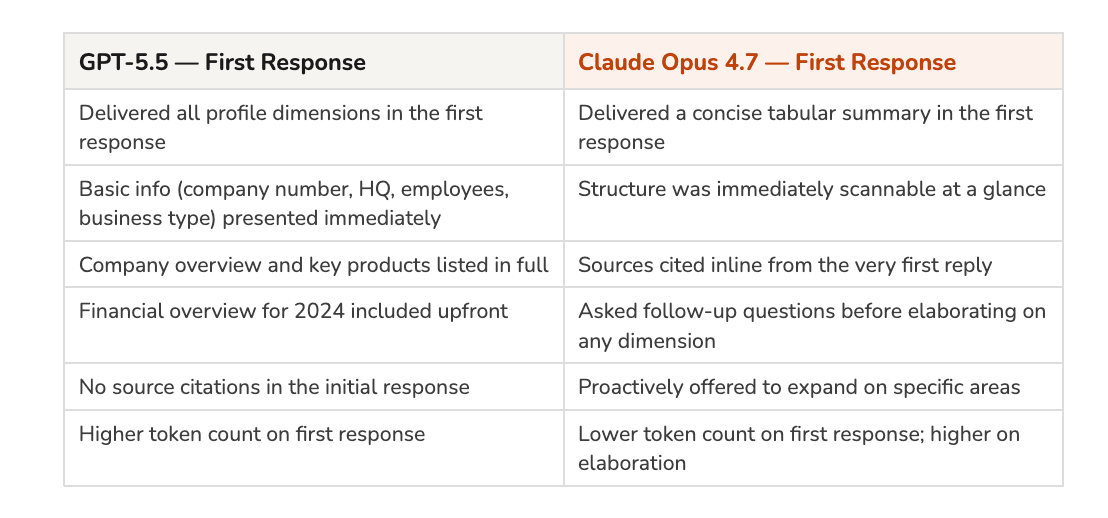
The most striking difference between the two models emerged in the very first response to the prompt “Share company profile for ABC.XYZ.” Both models immediately invoked their tools and began retrieving data. But how they chose to present their initial output revealed fundamentally different interaction philosophies.
The Elaboration Test: What Happened on Follow-Up
The most instructive part of the evaluation was what happened when we asked both models to elaborate on products and services. The two models’ divergent first-response strategies resulted in very different elaboration dynamics.
GPT-5.5 on follow-up: Because GPT-5.5 had already delivered significant product and service detail in its first response, the elaboration request produced incremental information. The model added depth where it could, but the marginal value of the follow-up was limited by the fact that the first response had already covered most of the ground. This is not a weakness — it’s the logical consequence of a breadth-first strategy.
Claude Opus 4.7 on follow-up: Because Claude Opus 4.7 had deliberately held back detail in its first response, the elaboration request unlocked a substantially richer breakdown. The model delivered a highly organised, category-separated analysis covering: consumer services (Search, Maps, Gmail, YouTube), platform and developer products (Google Cloud, Android, Play Store), hardware (Pixel, Nest, Chromecast), and subscription services (Google One, YouTube Premium, Workspace). Each category was treated as a distinct structural unit with its own coverage. The information density per token on this elaboration response was noticeably higher than the equivalent GPT-5.5 follow-up.
This difference in elaboration richness has practical implications for agent design. If your workflow is single-shot — one prompt, one response, downstream processing — GPT-5.5’s approach is more efficient. If your workflow is conversational or iterative — with human review and follow-up questions — Claude Opus 4.7’s approach may produce higher total output quality across the interaction.
Source Transparency and Auditability
One of the most practically significant differences between the two outputs was source citation. Claude Opus 4.7 cited sources inline from its very first response, making it straightforward for a human reviewer to verify claims and trace data back to its origin. GPT-5.5’s initial response did not include source citations, making it harder to audit the output without independently re-searching the underlying data.
For enterprise use cases where outputs will be reviewed by compliance teams, presented to executives, or used to inform significant business decisions, source transparency is not a cosmetic feature — it is a risk management requirement. The inability to quickly audit where a piece of data came from can be a blocker for adoption in regulated industries.
Quantitative Scoring and Trace Analysis
Evaluation Results
The structured evaluation produced results that aligned with the qualitative observations, while also surfacing important nuance about score variance across traces.
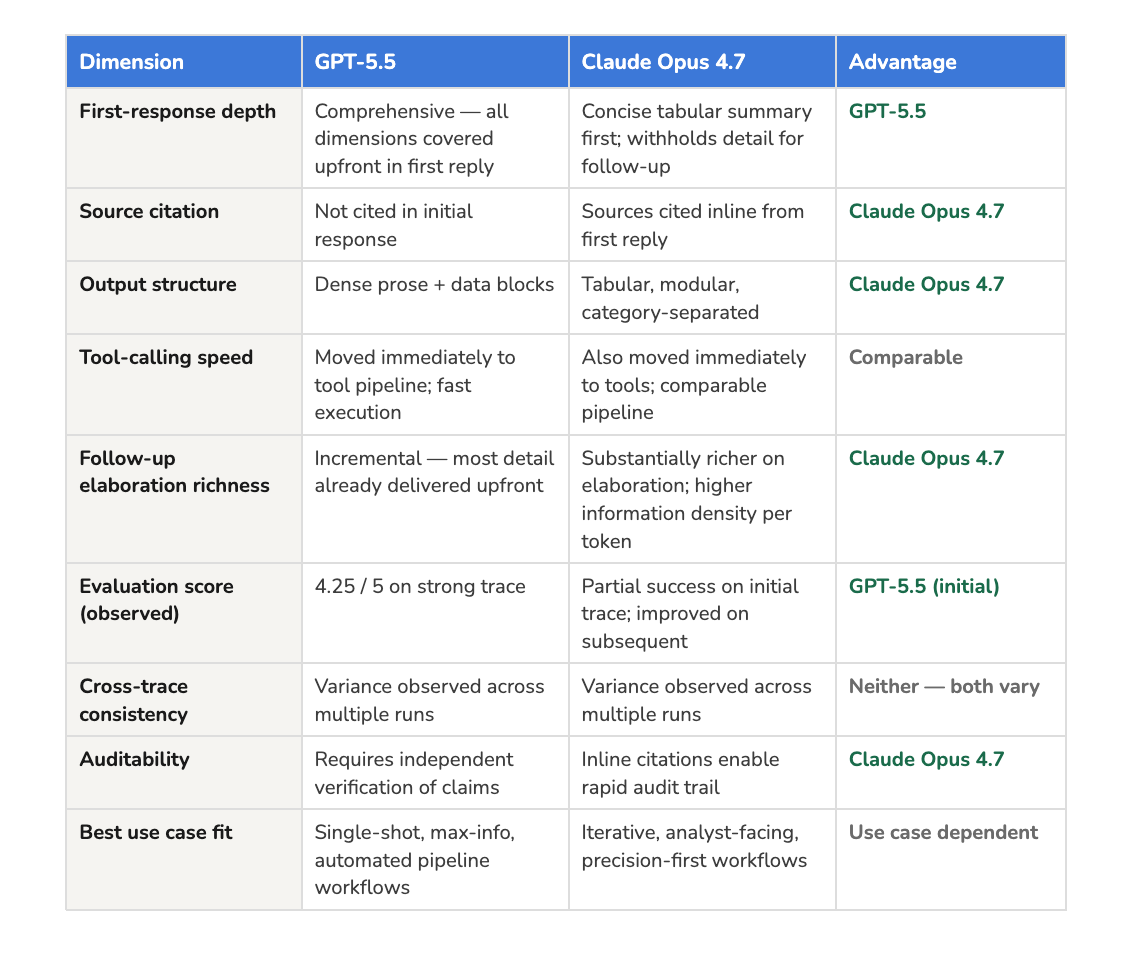
GPT-5.5 scored 4.25 out of 5 on a strong evaluation trace. Claude Opus 4.7’s initial trace was assessed as partial success with critical limitations — the evaluator noted that the agent response required significant effort and showed partial success but with constraints that impacted quality and correctness. Subsequent traces for Claude Opus 4.7 performed better, consistent with the probabilistic nature of LLM output.
Why Single-Trace Results Are Misleading
The initial score difference between the two models could easily be misread as evidence that GPT-5.5 is the superior model for this use case. It is not — or at least, a single trace is not sufficient evidence to draw that conclusion. LLM outputs are probabilistic: the same model, the same prompt, and the same tools can produce meaningfully different outputs across runs, depending on temperature settings, the state of external data sources at retrieval time, and other stochastic factors.
The appropriate interpretation of a single trace result is: “this is a data point, not a verdict.” The pattern across multiple traces — the mean score, the score variance, and the frequency of different failure modes — is the only reliable signal. SimplAI logs all traces automatically, making this kind of longitudinal analysis a standard feature of the development workflow rather than a separate data engineering effort.
Head-to-Head: Full Dimension-by-Dimension Breakdown
Decision Framework: When to Use GPT-5.5 vs Claude Opus 4.7
Choose GPT-5.5 When…
GPT-5.5’s breadth-first output strategy is best suited to workflows that prioritise maximum information retrieval in the fewest possible interaction turns:
- Single-shot automated pipelines: If your agent feeds its output directly into a downstream system — a database, a report generator, a dashboard — and you need everything in one pass without follow-up interaction, GPT-5.5’s upfront comprehensiveness is a structural advantage.
- High-throughput batch processing: When running the same agent task across hundreds or thousands of inputs where interaction latency is a bottleneck, minimising round-trips is critical. GPT-5.5’s tendency to front-load information reduces the need for follow-up calls.
- Workflows where citation is handled downstream: If your pipeline has a separate citation or sourcing layer, the absence of inline citations in GPT-5.5’s initial output is not a limitation — it’s simply a division of responsibility.
- Tasks requiring comprehensive coverage as the primary success criterion: When the evaluation rubric places the highest weight on completeness, and completeness is measured in the first response, GPT-5.5’s approach aligns with the scoring criteria.
Choose Claude Opus 4.7 When…
Claude Opus 4.7’s structured, cited, iterative output strategy is best suited to workflows that prioritise quality, auditability, and human-in-the-loop review:
- Analyst-facing or executive-facing outputs: When a human will read the agent’s output and make decisions based on it, Claude Opus 4.7’s inline citations, tabular structure, and modular organisation make the output significantly easier to navigate, verify, and trust.
- Regulated industries with compliance requirements: In financial services, healthcare, legal, and other regulated domains, the ability to trace every claim back to a source is not optional. Claude Opus 4.7’s citation behaviour directly supports this requirement.
- Conversational or iterative agent workflows: When the agent interaction is designed to be multi-turn — with the user refining their request across several exchanges — Claude Opus 4.7’s tendency to ask clarifying questions and withhold detail until specifically requested produces better total output quality across the conversation.
- Tasks requiring categorical organisation: For outputs that need to be divided into clearly separated sections — as in the products and services breakdown where consumer, platform, hardware, and subscription were treated as distinct categories — Claude Opus 4.7’s structural instincts are a significant asset.
When You Genuinely Don’t Know Yet
This is the most common situation for teams at the start of a new agent project, and it’s the most important case to address honestly. If you’re building a new use case and are not certain which model will perform better, the correct answer is: do not guess. Evaluate.
Build your agent once in SimplAI with the full tool stack and system prompt. Publish two versioned copies — one with GPT-5.5, one with Claude Opus 4.7. Run both against your actual prompts. Configure an evaluator rubric that reflects your real quality criteria. Review the traces. Let the scored data tell you which model produces better output for your specific task. This process takes hours, not weeks, and it produces a defensible, evidence-based answer rather than an informed guess.
Step-by-Step: Running Your Own Model Evaluation in SimplAI
For teams who want to replicate this evaluation methodology on their own use case, here is a precise, step-by-step guide.
- Build one agent, not two. Create your agent in SimplAI with the complete tool stack, system prompt, and orchestration logic. Do not create separate agents for each model — use SimplAI’s model picker to switch between models within the same agent configuration.
- Publish before you preview. Before running any test interactions, publish your agent configuration with a descriptive version label (e.g., “GPT-5.5 v1” or “Opus 4.7 v1”). This locks the configuration at a known state and ensures your evaluation is always running against a defined baseline.
- Write your evaluator with AI assistance. Use SimplAI’s AI-assisted evaluator builder. Describe your evaluation goal in plain language. Review the suggested rubric and adjust the scoring criteria to reflect your specific quality requirements. Save the evaluator as a template so it applies consistently to all future traces.
- Run the same prompt against both model versions. Use the exact same prompt — word for word — for both model runs. Any difference in the prompt introduces a confounding variable that makes it impossible to attribute performance differences to the model alone.
- Review individual traces before looking at aggregate scores. For each model run, open the full trace in SimplAI’s trace viewer. Read the tool calls, the intermediate outputs, and the model’s reasoning chain. Understand why the model produced the output it did before drawing conclusions from the score.
- Run multiple traces before drawing conclusions. LLM outputs are probabilistic. Run a minimum of 10–20 traces per model version before making a model selection decision. Pay attention to both the mean score and the score variance — a model with a high mean but high variance may be less suitable for production than a model with a slightly lower mean but more consistent performance.
- Iterate and re-evaluate. Model evaluation is not a one-time event. As your agent evolves — new tools, refined prompts, updated skills — publish new versions and re-evaluate. SimplAI’s version history and evaluation logs make this a continuous, low-friction process rather than a disruptive re-engineering effort.
Broader Implications: The Shift to Ongoing Model Optimisation
The finding that neither GPT-5.5 nor Claude Opus 4.7 is categorically superior is not a limitation of this evaluation — it is its central insight. The era of the single best LLM is over. At the frontier of model capability, the meaningful differences between top models are not in raw intelligence — they are in behaviour, style, interaction patterns, and fit for specific tasks.
This has a direct implication for how enterprise teams should structure their AI development practice. The teams that build the most reliable, highest-performing AI agents in 2026 will not be the ones that found the perfect model at launch. They will be the ones that built the infrastructure to keep evaluating and optimising model selection as an ongoing practice.
That infrastructure has three components:
- A platform that supports model-agnostic agent architecture: Your agent’s logic, tools, and prompts should be portable across models without re-engineering. SimplAI is designed for this from the ground up.
- A rigorous evaluation methodology: Structured rubrics, consistent test prompts, multi-trace analysis, and version-controlled baselines. Not intuition, not one-shot comparisons, not lab benchmarks.
- A culture of evidence-based model selection: The discipline to run the evaluation before making the decision, and the infrastructure to revisit the decision as the model landscape evolves.
SimplAI provides the first component out of the box. This report documents the second. The third is a practice your team builds over time — and the sooner you start, the larger the compounding advantage.
Conclusion
GPT-5.5 and Claude Opus 4.7 are both exceptional foundation models. In our controlled evaluation of a multi-tool enterprise company intelligence agent, GPT-5.5 demonstrated stronger first-response comprehensiveness and scored 4.25/5 on a strong evaluation trace. Claude Opus 4.7 demonstrated superior output structure, inline source citation, and elaboration richness on follow-up.
Neither model is the right answer for every enterprise agent use case. GPT-5.5 is better suited to single-shot, automated, high-throughput pipelines. Claude Opus 4.7 is better suited to iterative, analyst-facing, compliance-sensitive workflows. For teams that don’t yet know which category their use case falls into — run the evaluation. Let the data decide.
The most important takeaway from this evaluation is not which model scored higher on a single trace. It is that model selection is an ongoing optimisation problem, not a one-time architectural decision. The teams that treat it as such — building the evaluation infrastructure and the discipline to run it regularly — will consistently outperform those that don’t.
Is GPT-5.5 better than Claude Opus 4.7 for enterprise AI agents?
Neither model is categorically better. In our evaluation, GPT-5.5 scored 4.25/5 on a strong trace and delivered higher first-response comprehensiveness. Claude Opus 4.7 produced more structured, source-cited outputs and performed better on iterative, follow-up-driven tasks. The right choice is use-case dependent. The only reliable way to determine fit is to run a scored, multi-trace evaluation on your actual prompts and tools — not to rely on lab benchmarks or published comparisons including this one.
How do you evaluate LLM performance for a production AI agent?
Build your agent once with the complete tool stack and system prompt. Publish versioned copies with different models. Run identical prompts through both versions. Use a structured evaluation rubric — a numerical scale with defined criteria per score band — to score each output consistently. Review individual traces (not just aggregate scores) to understand why the model performed well or poorly. Run a minimum of 10–20 traces per model version before drawing conclusions. SimplAI supports this entire workflow natively.
Can you switch LLM models in an AI agent without changing your code?
Yes — if your agent is built on a model-agnostic platform like SimplAI. In SimplAI, switching models is a single configuration change in the model picker. All prompt logic, tool integrations, orchestration behaviour, and evaluation infrastructure remain identical. This is the architectural precondition for genuine model comparison: if switching models requires re-engineering the agent, you cannot isolate model behaviour as the single variable you’re testing.
What is the best LLM for company research and intelligence agents?
Based on our evaluation: GPT-5.5 is stronger for single-shot comprehensive outputs where a human-in-the-loop is not reviewing the result. Claude Opus 4.7 is stronger for structured, cited outputs where an analyst or compliance officer will review the content. For fully automated pipelines that ingest everything at once, GPT-5.5’s breadth-first approach may be preferable. For analyst-facing workflows where source transparency matters, Claude Opus 4.7’s inline citation behaviour is a significant structural advantage.
Why do LLM evaluation scores vary across runs?
LLM outputs are probabilistic. The same model, the same prompt, and the same tools can produce meaningfully different outputs across runs due to temperature settings, the state of external data sources at retrieval time, and inherent stochasticity in the generation process. This is why single-trace results are data points, not verdicts. Reliable model selection requires multi-trace evaluation — analysing the mean score, score variance, and frequency of different failure modes across a sufficient sample of runs.
Ready to run your own model evaluation?
Build your agent once on SimplAI. Publish multiple model versions. Run scored evaluations. Let the trace data decide which model fits your use case — no guesswork, no re-engineering.
Author bio