Quick Answer
Human approval before AI agent execution isn’t a generic safety toggle — it’s an architectural decision about where a checkpoint sits in the agent’s workflow: between diagnosis and recommendation, or between recommendation and execution. In IT operations, the safer default keeps agents observe-only or recommendation-only, requires explicit human approval before any configuration change executes, and reserves full autonomy for narrow, pre-approved, low-blast-radius actions. SimplAI orchestration layer implements this as a configurable gate inside the agent’s workflow, not as a bolt-on approval step.
Where the Guardrail Actually Needs to Sit
During a recent SimplAI Agentic AI Operating System walkthrough, a partner engineering lead described exactly how he wanted an AI agent to behave the next time a major incident hit his environment. He wasn’t asking for a feature. Without quite meaning to, he was describing an architecture.
“I don’t want the agent to go ahead and, you know, execute it by itself. It should give me recommendations where, as an engineer, there should be a guardrail, basically, where I’ll go, I’ll check the configurations, whether it is correct, whether it is matches, then I’ll go execute it.”
He then described the second half of the same workflow — what’s allowed to happen once he says yes:
“For this major incident, this was a root cause analysis that was found. And to fix this, these are the changes that you need to do in terms of your configuration, XYZ, XYZ. It should give me that recommendation. Let’s say once I approve the recommendation, then the orchestration layer comes into picture. It should go execute.”
Read closely, that’s not one requirement. It’s four, stacked in sequence: how the agent forms a diagnosis, how it turns that diagnosis into something a human can actually check, exactly where the human’s yes-or-no sits in the sequence, and what’s allowed to happen automatically once that yes is given.
Most conversations about “human-in-the-loop” AI collapse all four into a single question: is a human involved, yes or no. That framing is too blunt to build against. It says nothing about where in the pipeline the human sits, what they’re reviewing when they get there, or what happens if they’re not available.
In IT operations — where the entire point of deploying an agent is to move faster than a human could alone — getting that placement wrong is exactly as risky as skipping the checkpoint altogether. An approval step bolted onto the wrong point in the workflow either slows every routine action to the pace of a Slack message, or waves through changes that should never have run unsupervised.
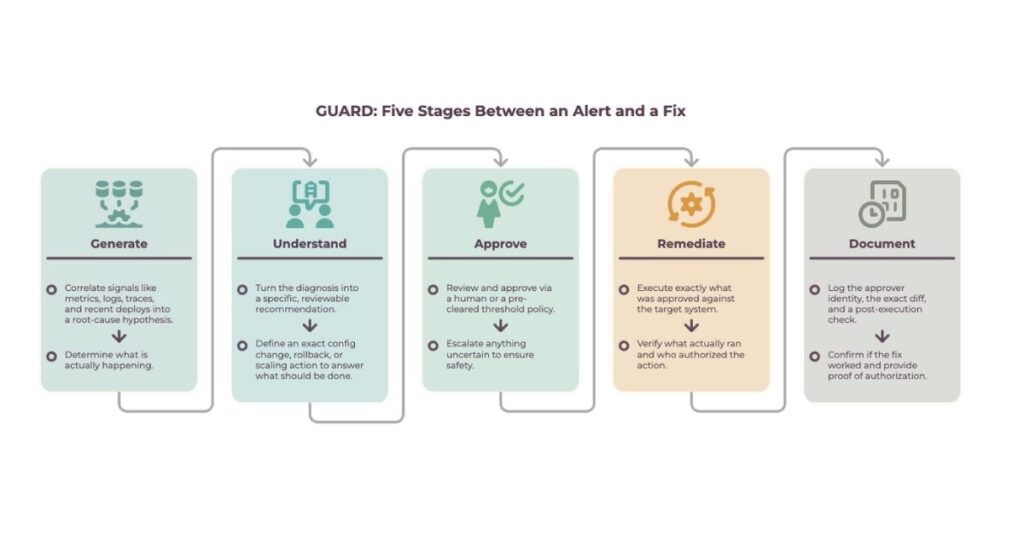
GUARD: Five Stages Between an Alert and a Fix
We built this partner’s requirement out into a five-stage pattern we call GUARD — Generate, Understand, Approve, Remediate, Document. It’s the execution-control counterpart to two patterns we’ve written about separately: VAULT, which governs what an agent is allowed to know and touch, and TRACE, which governs what gets logged once it acts. GUARD sits between the two — it’s the layer that decides what an agent is allowed to do next, and who, or what policy, gets to say yes.
| Stage | What happens | Who / what acts | The question it answers |
|---|---|---|---|
| Generate | Agent correlates signals — metrics, logs, traces, recent deploys — into a root-cause hypothesis | Agent, observe-only | What is actually happening? |
| Understand | Agent turns the diagnosis into a specific, reviewable recommendation: an exact config change, rollback, or scaling action | Agent, recommendation-only | What should we do about it? |
| Approve | A human reviews and approves, or a pre-cleared threshold policy approves automatically; anything uncertain escalates | Engineer or threshold policy | Who — or what policy — decided this was safe to run? |
| Remediate | The orchestration layer executes exactly what was approved, against the target system | Orchestration layer | What actually ran, and who authorized it? |
| Document | The system logs approver identity, the exact diff, and a post-execution check on whether the fix worked | System — audit log + verification | Did it work, and can we prove who approved it? |
The rest of this piece walks through each stage in the context this partner used: major incident management. MIM is the sharpest test of getting the Approve stage right, because blast radius is already elevated and the system is already broken. That’s exactly the moment a wrong automated change does the most damage — and exactly the moment the audit trail matters most if something later has to be explained to a regulator.
What Is an Observe-Only AI Agent?
An observe-only agent sits at the Generate stage of GUARD. It watches telemetry — error rates, latency, logs, recent deploys, configuration drift — and correlates that against known failure signatures. It doesn’t propose a fix. It doesn’t touch anything. Its entire job is to compress the time between “something is wrong” and “here is what’s actually wrong,” which in most incident postmortems is where the majority of the clock gets eaten.
In a major-incident context, this is the tier that catches the pattern an on-call engineer would otherwise spend the first fifteen minutes of a bridge call establishing manually — correlating a spike in failed transactions with a configuration change that shipped forty minutes earlier, rather than chasing three unrelated hypotheses at once. Observe-only agents are low-risk by construction: there’s nothing to approve, because nothing is being proposed yet. That makes this the tier every IT operations team should be comfortable deploying broadly, even in production, even on the systems they’re most protective of.
What Is a Recommendation-Only AI Agent?
A recommendation-only agent goes one stage further — Understand — and turns a root-cause diagnosis into something specific enough for a human to actually evaluate. Not “there’s a connection pool issue,” but “increase max pool size from 50 to 150 in payment-gateway-config.yaml,” along with the evidence behind that call and, where one exists, a second option — a rollback to the prior deployment, for instance.
This is where a lot of AIOps tooling quietly blurs the line this partner was drawing so precisely. A tool that surfaces “here’s a fix” and a tool that “goes ahead and executes it by itself” can look identical in a product demo — right up until the second one runs a change nobody reviewed. The distinction that matters architecturally is write access: a recommendation-only agent has none. It can read every system it monitors and propose a change in as much detail as an engineer would need to act on it themselves, but it cannot touch production directly. That boundary is what makes the next stage — Approve — a meaningful checkpoint rather than a formality.
Why Does Human Approval Before Execution Matter Most in Major Incident Management?
This is the stage the partner’s quote centers on almost word for word: check the configuration, confirm it matches, then execute. It’s worth being precise about why that sequence matters more during a major incident than it does during routine, low-stakes automation.
First, blast radius. A misconfigured recommendation applied to a system that’s already degraded doesn’t fail quietly — it compounds. A P2 with a wrong automated fix applied to it can become a P1. Second, evidentiary weight. In BFSI environments specifically, a change made to production infrastructure during an active major incident is exactly the kind of event that surfaces in a post-incident review, a regulator’s inquiry, or an audit sample — and “an approved change, executed by policy” is a fundamentally different answer than “the agent decided to run it.”
That second point isn’t hypothetical. Under RBI’s proposed FREE-AI framework, accountability for an AI-assisted action is expected to rest with a named person inside the institution, not be treated as a property of the model that generated the recommendation — a position the framework’s “People First” and Accountability principles both push toward. The EU AI Act takes a related but more technically specific stance: Article 14 doesn’t demand human review of every single action, but it does require that a high-risk system give a human the real, working ability to follow what it’s doing and stop it if something goes wrong — a design requirement, not a paper one. For a system managing production incidents at a bank or insurer, the safer default is the stricter reading: approval before execution, not just a theoretical ability to intervene afterward.
What Is Threshold-Based Autonomous Execution?
None of this means every action needs a live human tap before it runs. That’s where most conversations about human-in-the-loop AI go wrong — they treat “approved by a human” and “executed automatically” as opposites. They’re not. Threshold-based autonomous execution is still human-approved; the approval just happens in advance, as policy, rather than live, per incident.
A threshold policy typically clears an action for autonomous execution only when three conditions hold together: the fix pattern has been manually approved and verified enough times before that its outcome is predictable, the blast radius is genuinely limited — a stateless service restart, not a payment-routing change — and the action is reversible within the verification window described later in this piece. Get any one of those three wrong, and the action belongs back at a live approval gate.
| Action type | Recommended mode | Why |
|---|---|---|
| Restart a stateless service instance | Threshold-based auto | Low blast radius, fully reversible |
| Roll back to last known-good deployment | Threshold-based auto, once pre-validated | Predictable outcome after repeated manual approval |
| Scale compute for a degraded service | Threshold-based auto, within pre-set bounds | Reversible, bounded impact |
| Change a payment gateway or core banking config | Human approval, every time | Production financial infrastructure, elevated blast radius |
| Modify firewall or network segmentation rules | Human approval, often dual-control | Security-critical, hard to reverse cleanly |
| Delete or purge data | Never automate | Irreversible by definition |
The point of the table isn’t the specific rows — every environment’s risk tolerance differs. It’s the exercise itself: an architecture decision made once, action type by action type, is worth more than a blanket autonomy setting applied to the whole agent.
How Should AI Agent Escalation and Exception Handling Work?
Approval gates fail quietly if nobody has designed for what happens when the gate doesn’t get a clean answer. Four situations should always trigger escalation rather than a retry or a silent skip: the agent’s confidence in its own diagnosis falls below a set threshold, no approver responds within the incident’s SLA window, an approver explicitly declines the recommendation, or an executed fix fails its own verification check, covered next.
In a major-incident context, escalation should follow the same chain ITIL-based incident management already uses, rather than inventing a parallel one: from the on-call engineer to the incident commander, and from there to a cross-functional major incident team if the SLA window closes without resolution. The agent’s role during an escalation isn’t to keep proposing alternatives faster than the humans can evaluate them — it steps back to Generate, keeps gathering evidence, and hands a growing evidence trail to whoever picks up the escalation next. The failure mode worth designing against explicitly is an agent that treats a declined recommendation as a prompt to generate a second, more aggressive one.
How Do You Capture Who Approved What?
An approval that can’t be reconstructed afterward isn’t really an audit trail — it’s a log message. A defensible record of an approval needs five things: the approver’s actual identity, not a shared service account; a timestamp; the exact configuration diff that was approved, not a summary of it; whether the approval came from a live human tap or a threshold policy, and which policy; and the outcome once it ran.
This is where the compliance case for getting the Approve stage right stops being abstract. RBI’s FREE-AI recommendations call for regulated entities to keep detailed, retained records of AI-driven actions and stand up a formal process for reporting AI-related incidents, so an audit trail exists independent of any single system’s own application logs. ISO/IEC 42001 goes further and names this as an explicit control rather than a best practice: Annex A.8.4 expects written procedures for how AI-generated decisions get reviewed, defined escalation routes, and a record of every override — because that’s the evidence an auditor asks for first, ahead of the AI system’s own design documentation. Neither requirement is satisfied by an agent that logs “config updated” after the fact. The approval itself — the who, the exact what, and the when — has to be captured as a first-class record, not reconstructed from application logs later.
How Do You Verify Whether the Remediation Actually Worked?
Execution isn’t the end of the workflow — it’s the point where the Document stage has to earn its name. A defensible remediation loop checks the same signals that triggered Generate — error rate, latency, whatever the original alert was — against a defined observation window, typically minutes rather than seconds, since some failure modes take a few cycles to reappear. If those signals return to baseline within the window, the incident is verified resolved and the audit record closes out with a “worked” flag. If they don’t, the system should trigger an automatic rollback where one exists, or escalate, rather than let the incident sit in a false-resolved state.
There’s a second, quieter benefit to building this step properly: it’s what eventually makes threshold-based autonomous execution defensible for a given fix pattern in the first place. A recommendation that’s been proposed, approved, executed, and verified successful a dozen times over is a fundamentally different risk proposition than one that’s never been checked. Without a verification loop, every fix stays a live-approval action forever, whether or not it still needs to be.
A Major Incident, Walked Through GUARD
Here’s how the five stages run together in a scenario close to what the partner in this piece was describing.
3:14 AM — Generate. A bank’s payment gateway starts throwing elevated latency and a rising rate of failed transactions. The observe-only agent correlates the spike with a configuration change that deployed 42 minutes earlier and flags connection-pool exhaustion as the probable root cause, opening a major incident record — transaction failure volume alone clears the bank’s threshold for “major,” independent of what caused it.
Understand. The agent proposes two options: raise the connection pool’s max size from 50 to 150 in the affected service’s config, or roll back the full deployment from 42 minutes earlier. It flags that the rollback would also revert an unrelated fix shipped in the same release.
Approve. The on-call engineer, paged automatically, opens the recommendation, checks the proposed pool size against the service’s known-good range, and approves the config change rather than the rollback — exactly the “I’ll check the configurations, whether it is correct, whether it matches” step described earlier.
Remediate. The orchestration layer pushes the approved change, tagged to the engineer’s identity and timestamped to the second.
Document. The system watches error rate and latency for the next ten minutes. Both return to baseline within six. The incident is marked resolved, and the record — exact diff, approver, timestamp, verification result — is ready for both the internal postmortem and, if it’s ever asked for, a regulator.
Nothing in that sequence required the agent to be smarter than the diagnosis it produced at 3:14. What made it fast and defensible was that the checkpoint sat in exactly one place: after the recommendation, before the change touched production.
How SimplAI Implements GUARD in the Orchestration Layer
This isn’t a theoretical model — it maps directly onto how SimplAI platform is built. Generate and Understand agents are configured in Agent Builder and Workflow Builder, using the same design patterns as SimplAI’s BFSI agent library.
Approval gates are a configurable node inside the orchestration layer itself — the same “orchestration layer comes into picture” step the partner described — rather than an external ticketing step bolted on afterward, so the approve / threshold / escalate decision lives in the same workflow definition as the fix itself, not in a separate system someone has to keep in sync.
TRACE, SimplAI’s observability framework, generates the Document-stage record — approver identity, exact diff, and the post-execution verification check — as one audit trail rather than three. And the threshold policies that let low-risk, well-verified fixes clear Approve automatically are governed the same way VAULT governs every other agent permission: as an explicit, reviewable policy, not an implicit setting buried in an agent’s configuration.
If your team is designing this for the first time, the sequencing question to start with isn’t “should this be automated.” It’s the one the partner in this piece answered instinctively: where, exactly, does the checkpoint sit, and what’s allowed to happen on both sides of it.
Frequently Asked Questions
What’s the difference between human-in-the-loop and human-on-the-loop AI?
Human-in-the-loop means a human reviews and approves before an action executes — the Approve stage in GUARD, live. Human-on-the-loop means a human can monitor and intervene, but the agent can act without waiting for a tap — closer to threshold-based autonomous execution with an always-available override.
What is threshold-based autonomous execution?
It’s an approval that happens in advance, as policy, rather than live per incident. An agent can execute automatically only for actions that meet pre-cleared conditions: a validated fix pattern, limited blast radius, and reversibility within a defined verification window.
What is the orchestration layer in agentic AI?
It’s the component that actually carries out an approved action against a target system — executing the change, not deciding whether to make it. In GUARD, it operates only at the Remediate stage, strictly after Approve.
Does the EU AI Act require a human to approve every AI agent action?
Not literally every action. Article 14 requires that a high-risk system be designed so a human can monitor, understand, and stop it if needed — a capability requirement, not a blanket rule that every action needs prior review. Whether prior approval is required in a given case depends on the system’s risk level and use case.
What should never be fully automated in IT incident remediation?
Irreversible actions — data deletion or purges chief among them — and changes to core financial or security infrastructure, like payment routing or network segmentation, where the cost of a wrong automated call is disproportionate to the time saved.
How does RBI’s FREE-AI framework treat AI-driven IT operations?
FREE-AI is currently a set of recommendations, not binding regulation, but its Accountability and People First principles push toward the same pattern described here: identifiable human decision-makers, board-level accountability for AI use, and auditable logs — recommendations that map closely onto the Approve and Document stages of GUARD.
Author bio